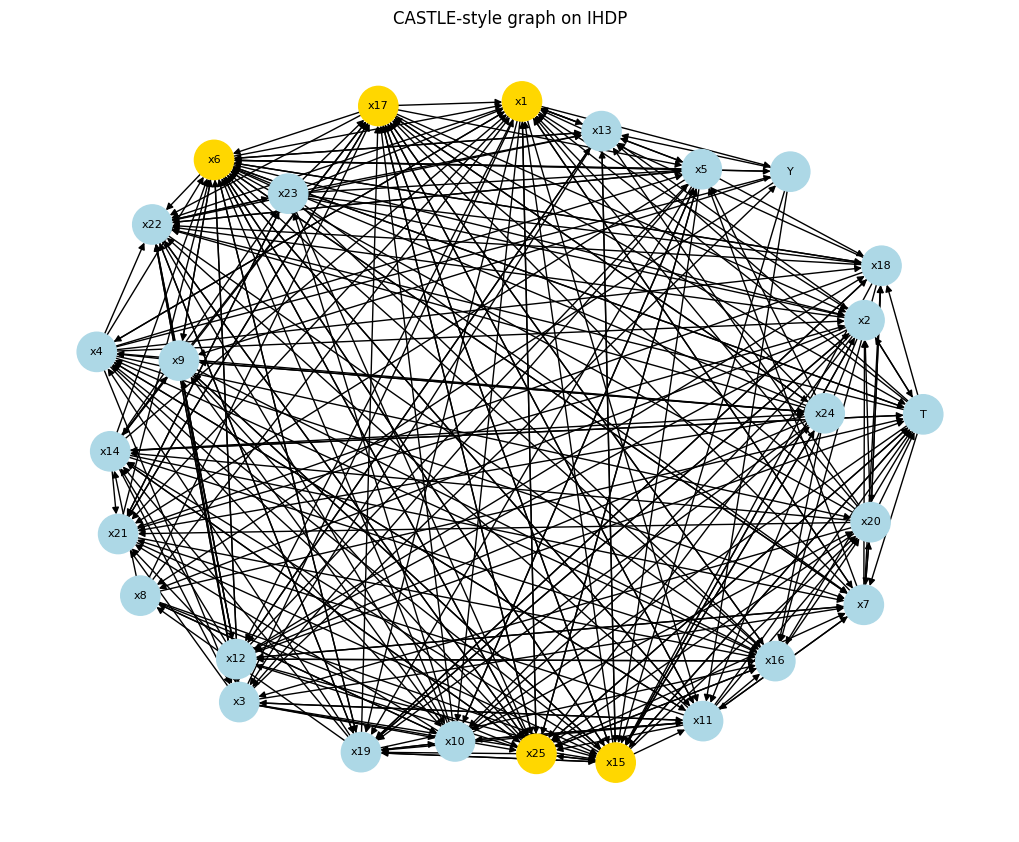
from pathlib import Path

def data_loading_ihdp(train_rate=0.8, replications=1, seed=42):
    """Load IHDP NPCI replicates (with synthetic fallback)."""
    import urllib.request
    base_url = "https://raw.githubusercontent.com/uber/causalml/master/docs/examples/data"
    repo = Path(".").resolve()
    local_dirs = [
        repo / "inst/examples/data",
        repo / "inst/exdata",
        repo.parent / "examples/data",
    ]
    dfs = []
    for i in range(1, 10):
        fname = f"ihdp_npci_{i}.csv"
        local_path = next((d / fname for d in local_dirs if (d / fname).exists()), None)
        if local_path is not None:
            dfs.append(pd.read_csv(local_path, header=None))
            continue
        url = f"{base_url}/{fname}"
        try:
            dfs.append(pd.read_csv(url, header=None))
        except Exception:
            pass
    if not dfs:
        rng = np.random.default_rng(seed)
        n = 747 * 9
        x_cont = rng.standard_normal((n, 6))
        x_bin = rng.integers(0, 2, size=(n, 19))
        x = np.column_stack([x_cont, x_bin])
        treatment = rng.integers(0, 2, size=n)
        mu0 = 0.3 * x[:, 0] - 0.2 * x[:, 1] + 0.15 * x[:, 2] + rng.normal(0, 0.2, n)
        tau = 1.0 + 0.2 * x[:, 3] - 0.15 * x[:, 4]
        mu1 = mu0 + tau
        y_factual = np.where(treatment == 1, mu1, mu0) + rng.normal(0, 0.3, n)
        y_cfactual = np.where(treatment == 1, mu0, mu1) + rng.normal(0, 0.3, n)
        df = pd.DataFrame(np.column_stack([treatment, y_factual, y_cfactual, mu0, mu1, x]))
    else:
        df = pd.concat(dfs, ignore_index=True)
    cols = ["treatment", "y_factual", "y_cfactual", "mu0", "mu1"] + [f"x{i}" for i in range(1, 26)]
    df.columns = cols
    if replications > 1:
        df = pd.concat([df] * replications, ignore_index=True)
    x = df[[f"x{i}" for i in range(1, 26)]].values.astype(float)
    t = df["treatment"].values.astype(float)
    y = df["y_factual"].values.astype(float)
    potential_y = df[["mu0", "mu1"]].values.astype(float)
    rng = np.random.default_rng(seed)
    idx = rng.permutation(len(x))
    n_train = int(train_rate * len(x))
    train_idx, test_idx = idx[:n_train], idx[n_train:]
    return {
        "train_x": x[train_idx], "train_t": t[train_idx], "train_y": y[train_idx],
        "train_potential_y": potential_y[train_idx],
        "test_x": x[test_idx], "test_potential_y": potential_y[test_idx],
    }


def preprocess_features(train_x, test_x):
    mu = train_x[:, :6].mean(axis=0)
    sd = train_x[:, :6].std(axis=0)
    sd[sd == 0] = 1.0
    a = train_x.copy()
    b = test_x.copy()
    a[:, :6] = (train_x[:, :6] - mu) / sd
    b[:, :6] = (test_x[:, :6] - mu) / sd
    return a, b


def build_causal_matrix(x, t, y, subsample=5000, seed=42):
    rng = np.random.default_rng(seed)
    Z = np.column_stack([x, t, y])
    idx = rng.choice(len(Z), size=min(subsample, len(Z)), replace=False)
    return Z[idx]